What tokentoll does
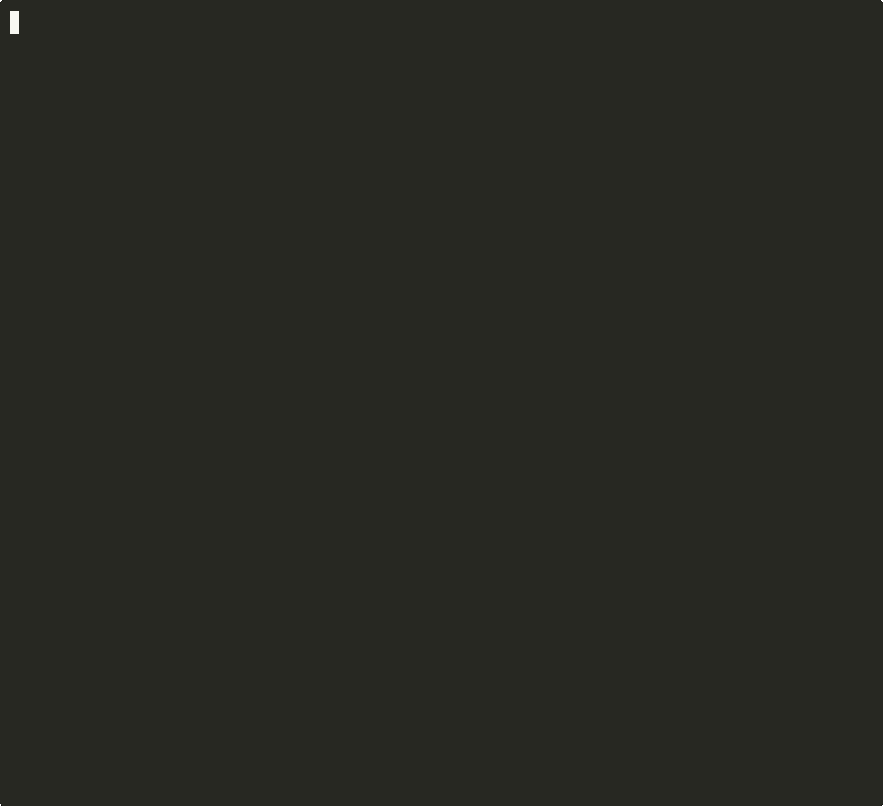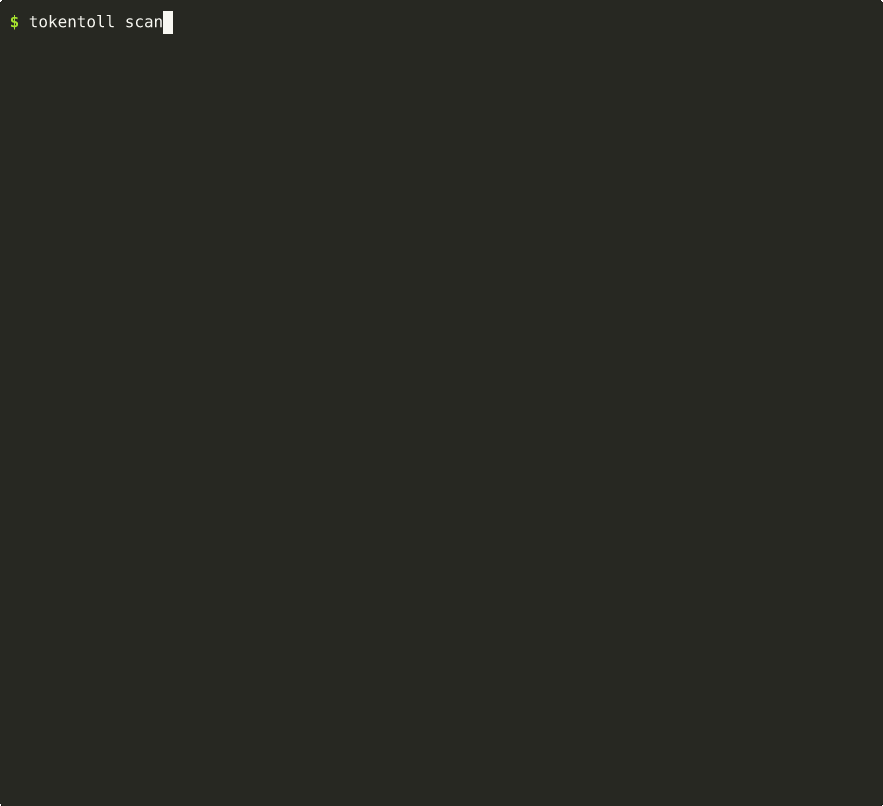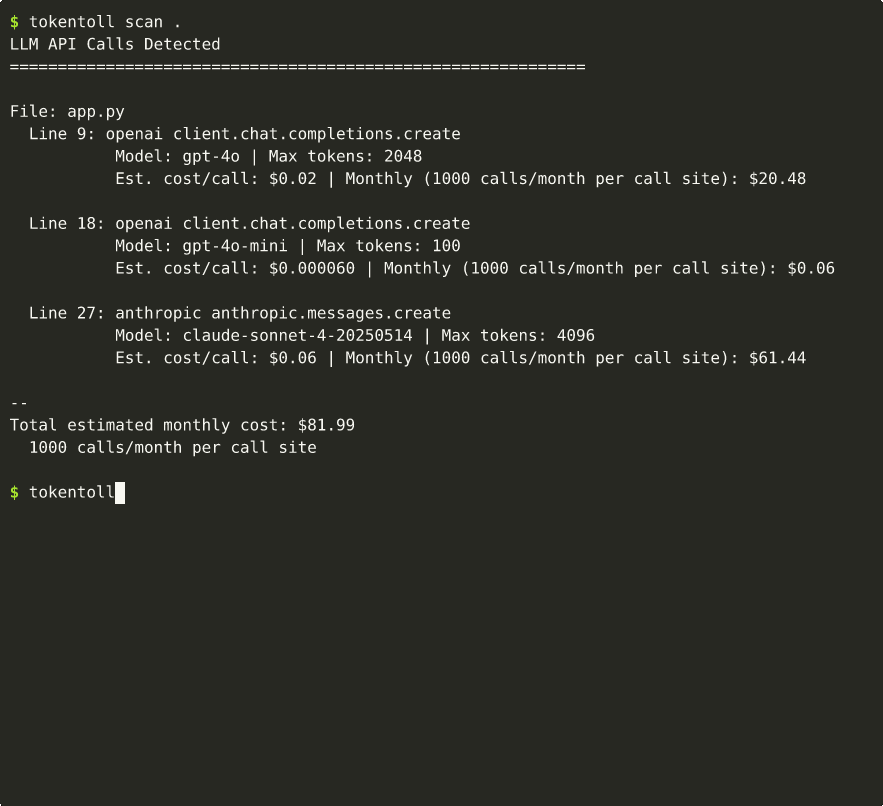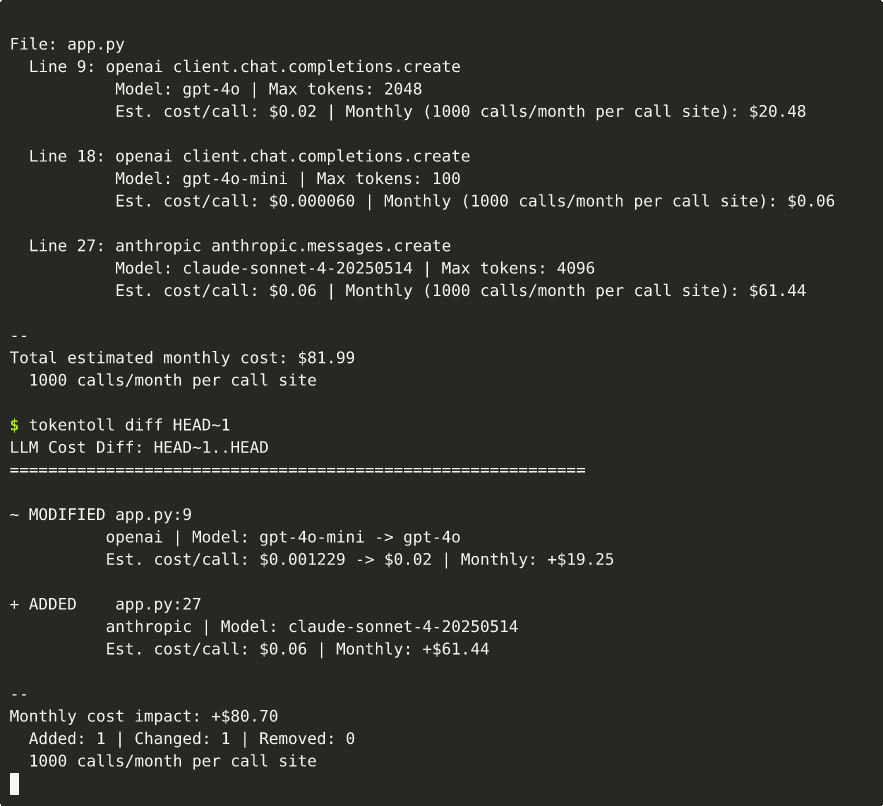
tokentoll finds LLM API calls in source
code, estimates their monthly cost and shows how a git diff changes that
estimate. Infracost does the same for Terraform and cloud resources. Code
changes that affect LLM cost include a different model, a new call site and a
removed max_tokens parameter.
This post describes the first version from May 2026, which scanned Python only. The last section lists what has changed since.
Architecture
tokentoll has five components:
- Scanner: walks Python files and passes each file to the detectors.
- Detectors: one per SDK (OpenAI, Anthropic, Google, LiteLLM, LangChain). Each finds the API calls of its SDK in the Python AST.
- Pricing engine: maps a model name to a cost per token, using a tiered name resolution, per-SDK default models for dynamic model names, and a local cache.
- Diff engine: matches old and new calls by file and line proximity.
- Output formatters: table (CLI), Markdown (PR comment), JSON.
Design decisions:
- The first version had no runtime dependencies. It used only the standard
library:
astfor parsing,jsonfor data,subprocessfor git,argparsefor the CLI andurllibfor fetching prices. - Each detector is one file that implements
can_handle()anddetect(). Adding an SDK requires no change to the scanner or the pipeline. - Prices come from LiteLLM's pricing database (2200+ models) and are cached in
~/.tokentoll/. tokentoll warns when the cache is stale and stops with an error when it is very old. - When a model name is dynamic, for example read from config or an environment variable at runtime, tokentoll prices the call with a default model for the SDK: gpt-4o for OpenAI, claude-sonnet for Anthropic, gemini-flash for Google. Calls with dynamic model names therefore still get a cost estimate.
Resolving model names to pricing entries
Code contains model="gpt-4o", while the pricing database has entries such as
gpt-4o, openai/gpt-4o, gpt-4o-2024-08-06 and azure/gpt-4o. tokentoll
tries these steps in order:
- Exact match
- Case-insensitive match
- Add the SDK prefix and match (
openai/gpt-4o) - Strip the provider prefix from database keys and match
- Strip a region prefix (
us.,eu.,apac.) - Strip a date suffix (
-2024-08-06,-20240806)
In the open-source projects I scanned, this resolved most model names.
Multi-pass constant propagation
Model names are rarely string literals at the call site. They pass through
variables, class attributes, config objects and **kwargs:
DEFAULT_MODEL = os.getenv("MODEL", "gpt-4o")

class Config:
    model: str = DEFAULT_MODEL

config = Config()
kwargs = {"model": config.model, "max_tokens": 2000}
client.chat.completions.create(**kwargs)
# tokentoll resolves: model="gpt-4o", max_tokens=2000
The engine repeats its passes until no resolved value changes. It follows
variable assignments, os.getenv() fallbacks, function defaults, class
attribute defaults, constructor arguments, dict contents and **kwargs
unpacking.
Configuration
A .tokentoll.yml file sets assumptions per project:
calls_per_month: 5000
default_models:
  openai: gpt-4o-mini
  anthropic: claude-haiku-3-20240307
overrides:
  - path: tests/
    calls_per_month: 100
Per-path overrides use longest-prefix matching, so test code, agent pipelines and batch jobs can have different call volumes and default models.
Test on twenty open-source codebases
I ran tokentoll on twenty open-source codebases, including NadirClaw, PraisonAI, agentops, swarms, honcho and atomic-agents. It detected OpenAI, Anthropic, Google and LiteLLM calls in all of them. In projects that load model names from config at runtime, the per-SDK default models still produced cost estimates.
Changes since the first version
Later versions also scan JavaScript and TypeScript (parsed with tree-sitter,
which is now a runtime dependency) and detect further SDKs such as the Vercel
AI SDK. A policy in .tokentoll.yml adds a PASS, WARN or FAIL verdict to the
PR comment and can fail the workflow. tokentoll also runs as an MCP server.
Pricing data ships with the package and can be refreshed from LiteLLM with
tokentoll update.
Usage
pip install tokentoll
tokentoll scan .
tokentoll diff HEAD~1
GitHub: github.com/Jwrede/tokentoll